Media · SME · In-house
A real-time Data Management Platform
Product strategy for a DMP processing 500M+ user events a day for 50+ media agencies: real-time ingestion, self-service segmentation, and a privacy-first (GDPR) data model.
Stack
- Apache Kafka
- Vertica (columnar)
- Redis
- Apache Spark
- SHA-256 hashing
- audit logs
Prior in-house work: scoped to my contribution.
Results
- 500M+user events processed a day200M+ by 2018
- 50+enterprise media-agency clients
- 99.95%SLA uptime
- 90%+client retention
Context
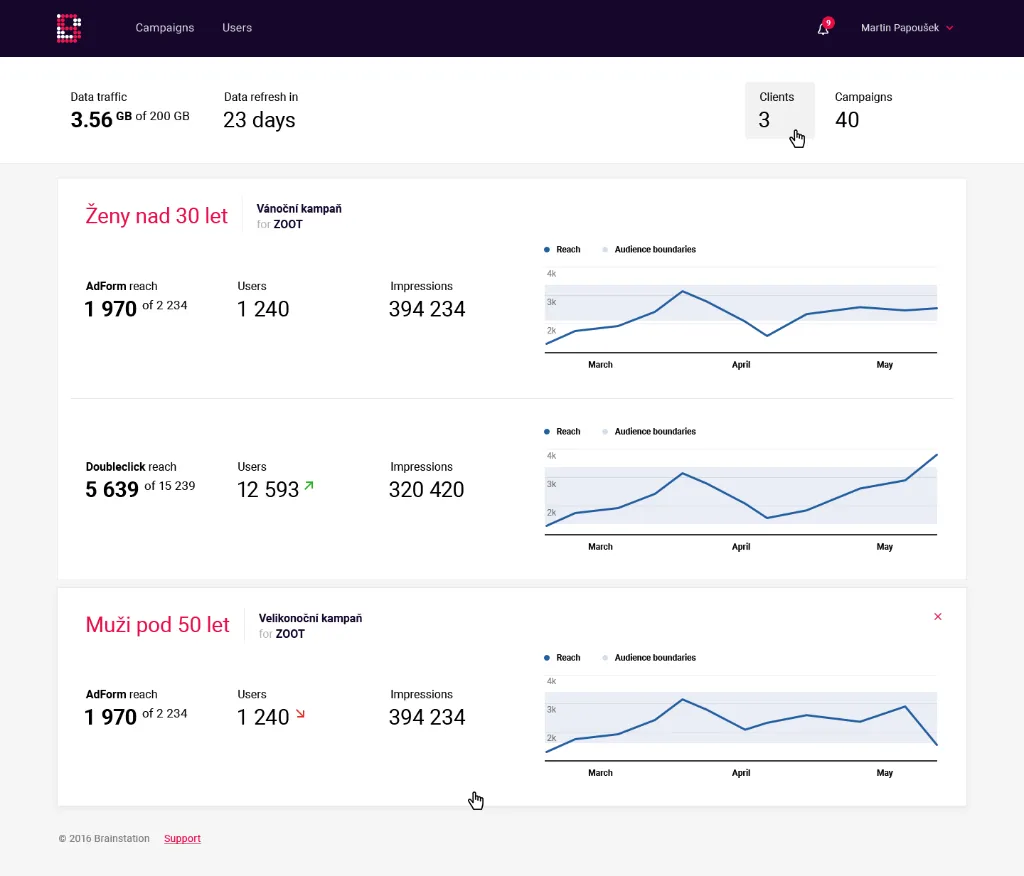
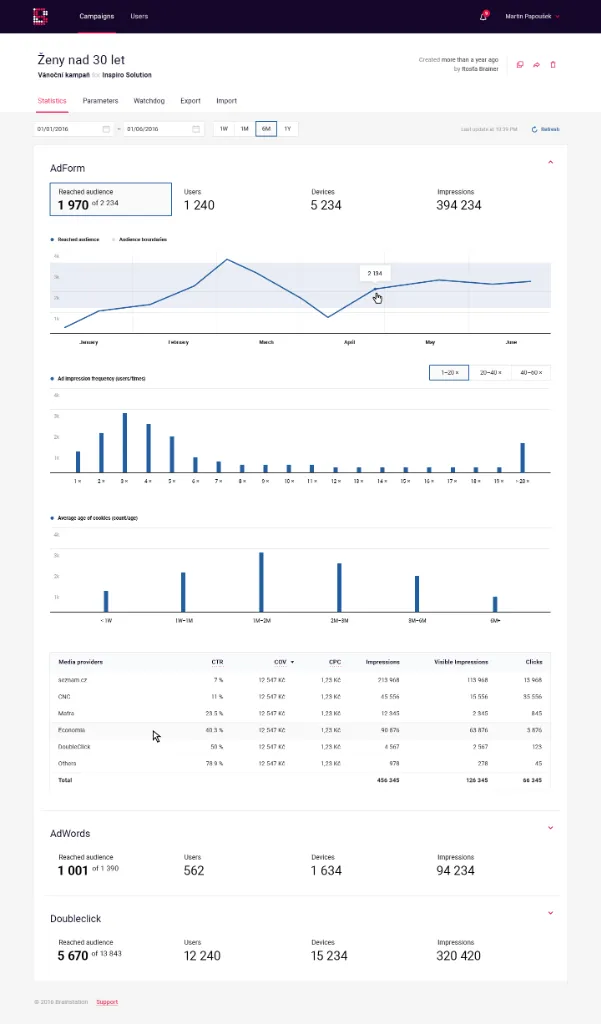
After Email Machine I joined a fast-growing Data Management Platform company as Product Manager, from 2016 to 2019. The platform served the major Czech and Central-European media agencies with real-time audience segmentation, cross-device tracking, and programmatic-advertising infrastructure. By the time I left it was handling 500+ million user events a day for 50+ enterprise clients and sitting under billions in programmatic ad spend. It was my first real big-data problem.
Problem
By 2016 programmatic advertising was growing fast, but agencies had a data-intelligence gap: they had the data and could not use it. Sources were fragmented across app, web and CRM; segmentation was manual and took weeks; there was no unified view of a user; and the rules were tightening toward GDPR. Stale, inconsistent segments were the result.
Approach
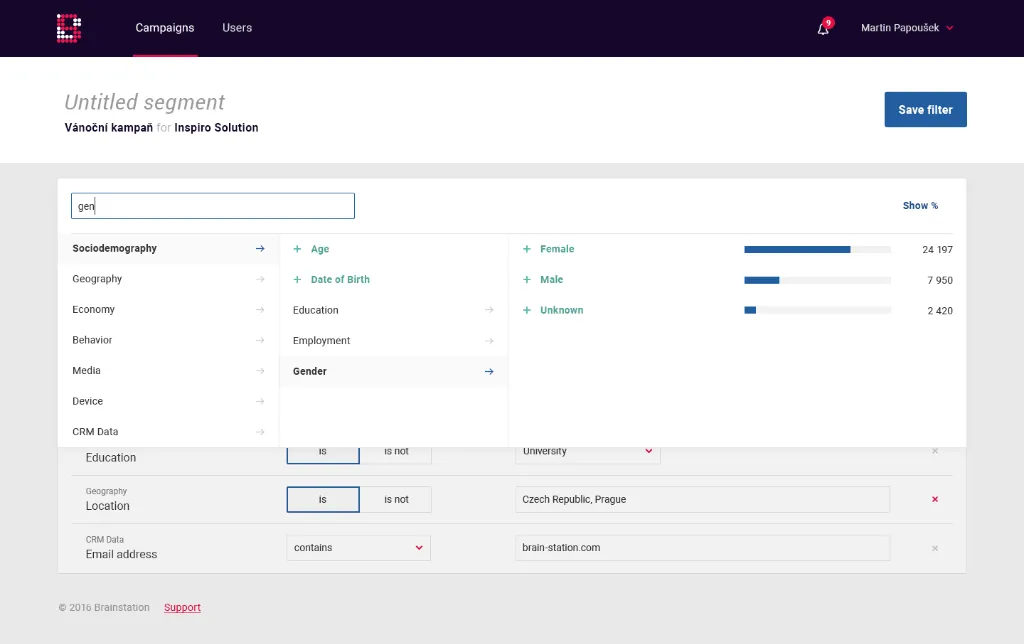
Three pillars. Unify: collect events from every source under one persistent user ID with cross-device matching, so targeting works off the whole journey, not isolated clicks. Self-serve: a visual segment builder for non-technical marketers with real-time query computation, taking segment creation from weeks to minutes. Privacy-first: first-party cookies, GDPR compliance, transparent handling and audit trails, turning the regulation into a reason to trust the platform rather than a constraint.
What I built
As Product Manager leading strategy for a 15–20-person team: the product direction across the three pillars, and the priority calls that shaped them, moving from fast ingestion to strict validation at the edge; the self-service segmentation UX; the GDPR and audit features shipped ahead of the deadline; and the roadmap into ML lookalikes. The platform runs on Kafka for ingestion, Vertica and Redis for storage, Spark for batch and streaming, with SHA-256 hashing and audit logs for privacy.
Platform
Results
500M+ events a day, up from 200M+ in 2018. 50+ enterprise agency clients, 99.95% SLA uptime, 90%+ retention. Delivered in three phases: MVP and 3–5 pilots in 2016–17, enterprise scale with cross-device and GDPR in 2017–18, then ML features and Central-European market leadership from 2019. Measured by daily event throughput, client count, retention, and SLA.
What I’d tell you if you’re facing this
Three things. Data quality is everything: we moved from fast ingestion to strict validation because fixing bad data downstream costs more than preventing it at the edge. Privacy is a feature: building privacy-first ahead of GDPR won enterprise trust rather than slowing us down. And complexity hides in platforms: engineers think a query is simple and marketers do not, so the UX work to make powerful infrastructure usable is not optional.